بسم الله
After talking about scheduling in the previous lesson, today we move to one of the pillars of operating systems: main memory management. We already touched a practical side of it in the virtual memory lesson of the C workshop; this lesson is the theoretical foundation it all rests on.
Background
A modern OS must allow large numbers of processes to sit in memory simultaneously for concurrent execution — and that is what makes memory management complex. There is quite a range of memory-management algorithms, and most require special forms of hardware support.
We assume primary memory is an array of individually addressable bytes, and the instruction-execution cycle generates a stream of memory addresses. The hardware responsible for managing them is the Memory Management Unit (MMU), which has no ability to infer an address’s purpose — it deals with numbers only.
Another essential point: the only general-purpose storage a CPU can access directly is main memory and registers; the processor cannot directly reach disk or other peripheral storage. Also, CPU access to main memory is many times slower than to registers — which is where caches, covered in the architecture series, come to help.
Protection via Base & Limit Registers
Hardware must provide a mechanism protecting each process’s allocated memory; assigning this job to the OS alone would carry such an extreme performance penalty as to be impractical.
A simple protection scheme:
- The system allocates process P one contiguous span of memory.
- The Base Register holds the lowest address allocated to P.
- The Limit Register holds the byte count of that allocation.
Using these two values, hardware checks every address generated by the program in user mode; any attempt to reach outside bounds results in a trap into the OS. Changing either register is a privileged instruction only the kernel executes — and the kernel naturally gets unrestricted access to all memory, a necessity for tasks like loading jobs and fetching syscall parameters:
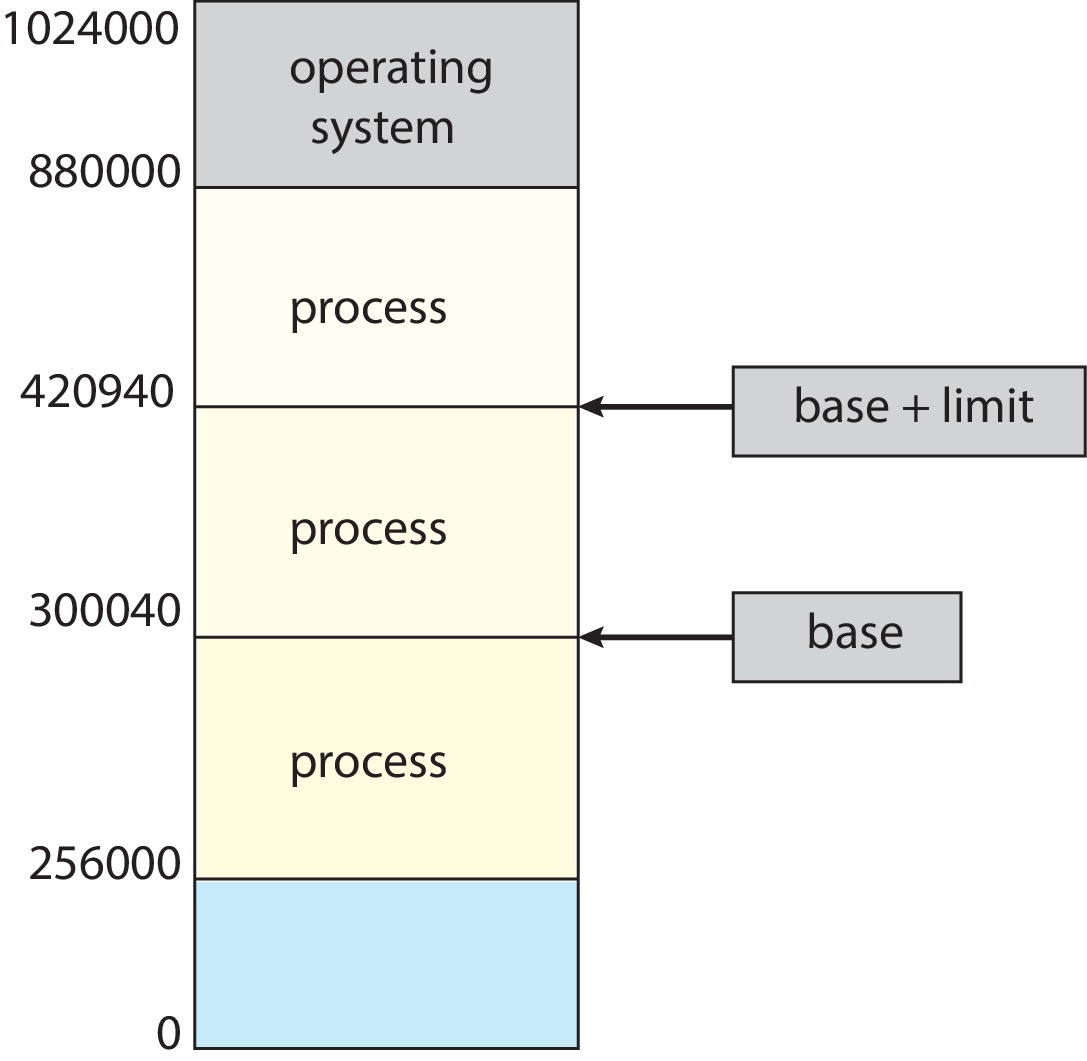 Figure (1): Base and limit registers define a logical address space
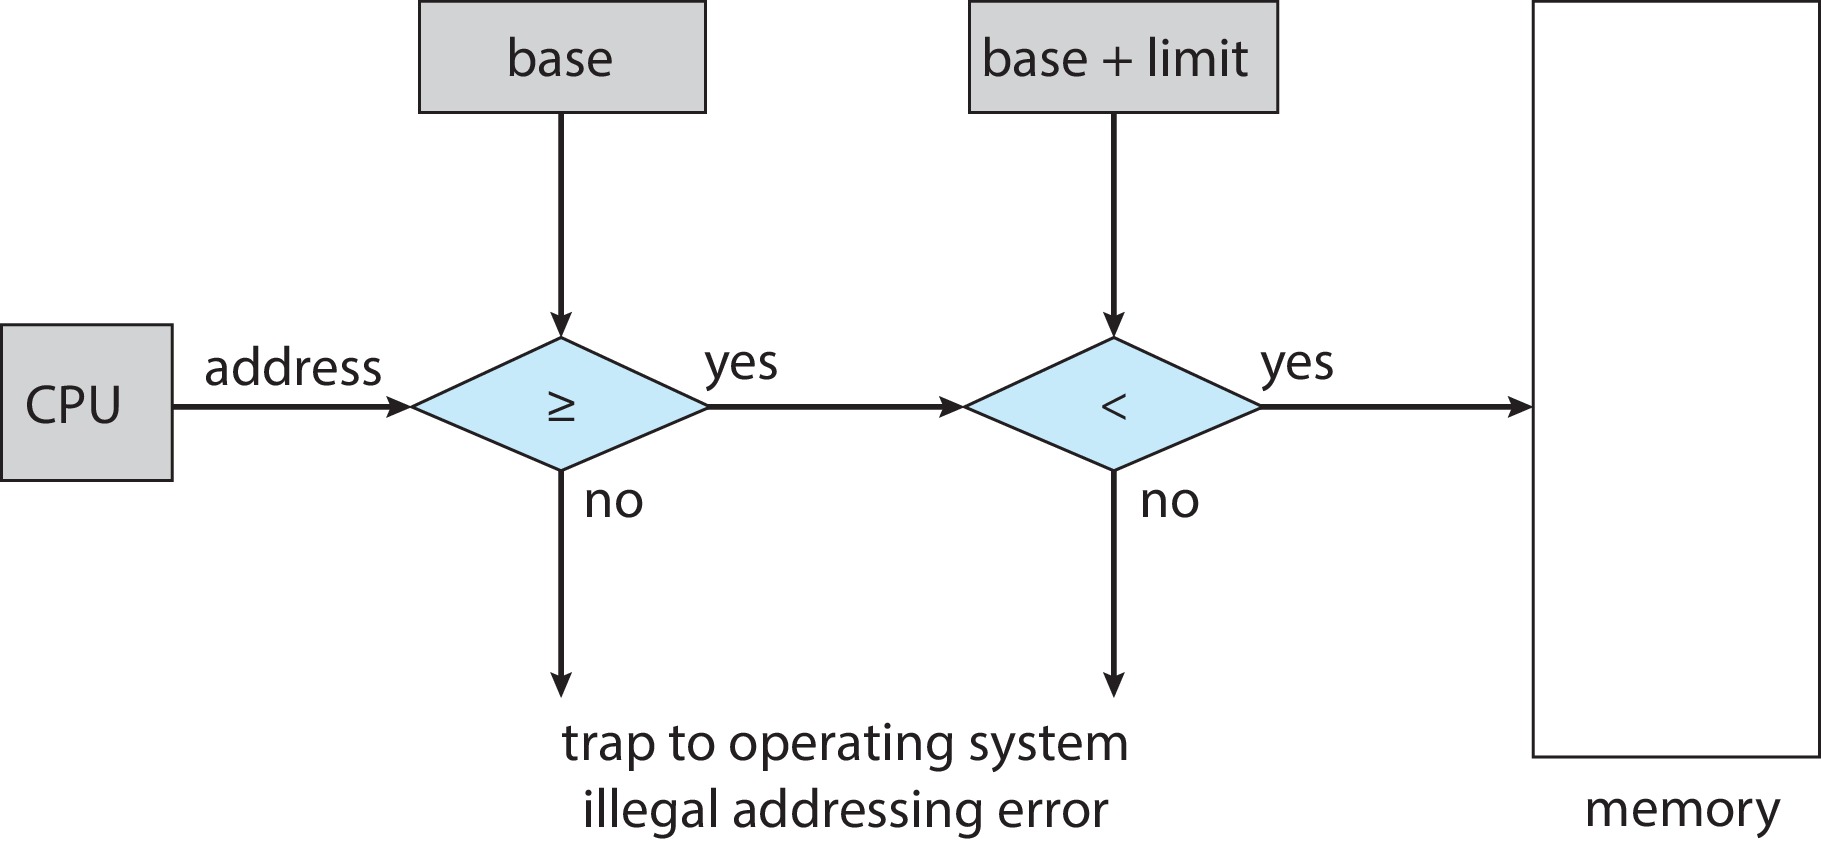 Figure (2): Hardware checking every user-mode address against the bounds
Address Binding
Addresses in source code are symbolic — like the variable name count. Typically the compiler binds those symbolic addresses to relocatable addresses given as offsets from the program’s base, later convertible to absolute addresses by the linker or loader. To allow relocating programs at runtime from one memory area to another, contemporary systems use special techniques requiring both hardware and OS support.
Logical Versus Physical Address
The addresses seen by the CPU are logical addresses, also called virtual. The addresses seen by the memory address register (MAR) are physical addresses.
The two spaces can be identical in simple systems, but under execution-time binding — the dominant paradigm — they are separate. While a process executes, MMU hardware performs the logical-to-physical mapping required during the fetch/decode/execute cycle. The user program deals exclusively with logical addresses, and the MMU translates one only when a memory access actually occurs.
In a simple scenario, the MMU might translate logical addresses in range 0..max into range R..R+max, where R sits in a relocation register similar to a base register:
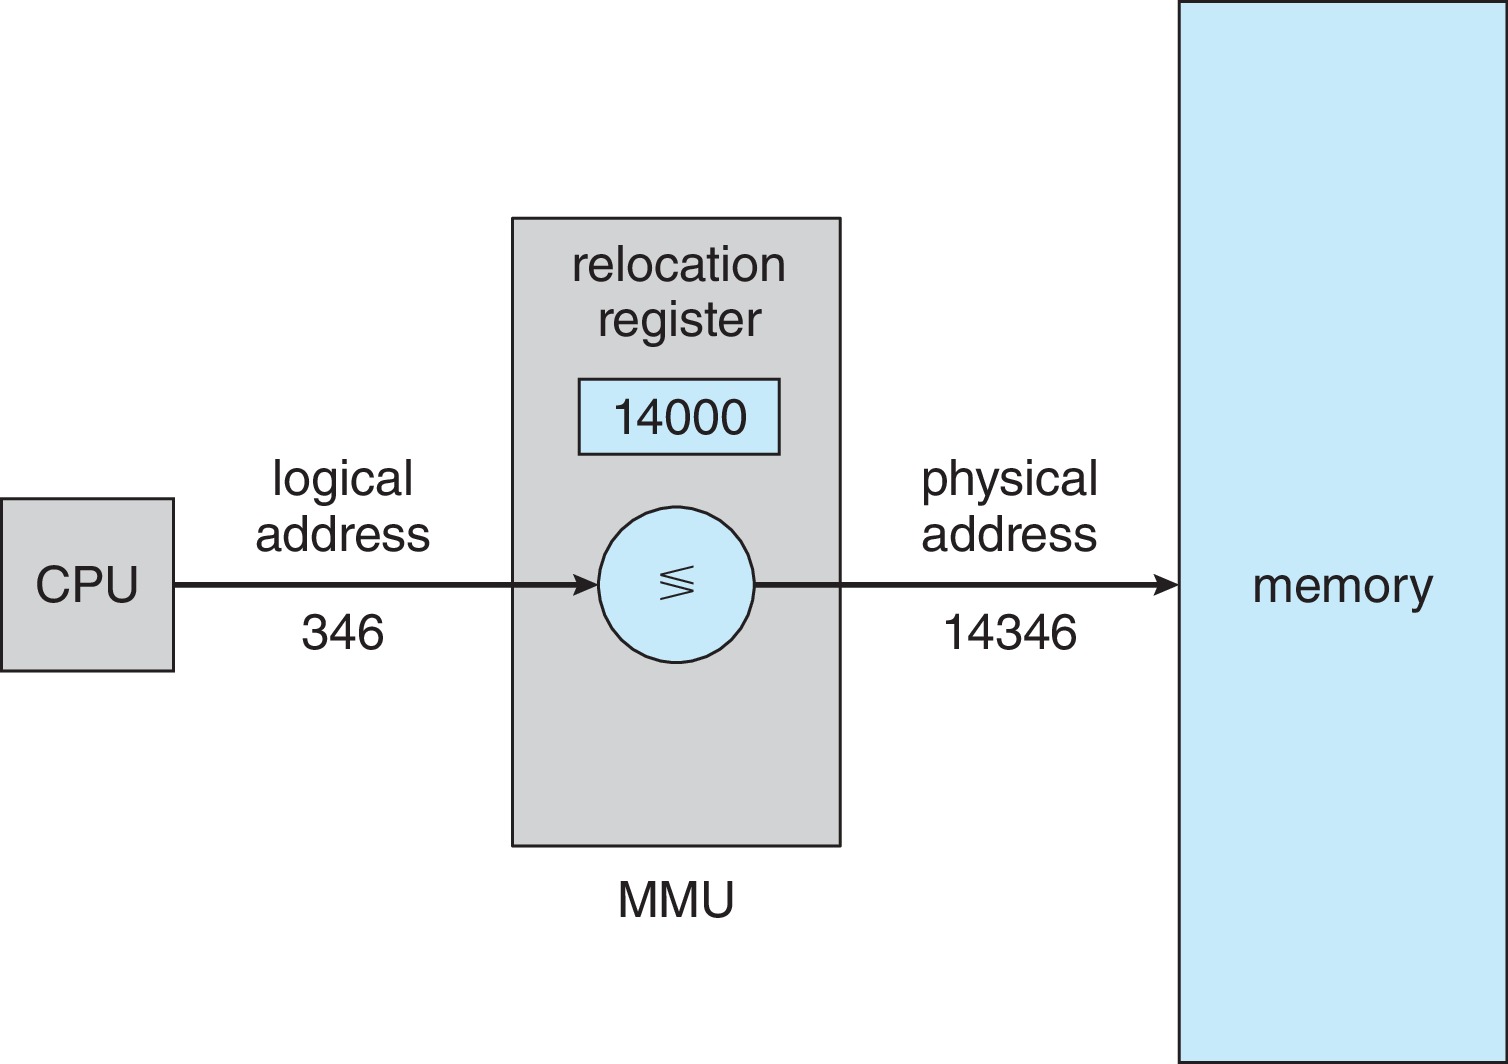 Figure (3): Dynamic relocation using a relocation register
Dynamic Loading & Dynamic Linking
Under dynamic loading, a routine is not loaded until called; each routine has a disk image in relocatable load format, and routines never called are never loaded — considerable memory savings. This can be implemented purely within user processes, no special help needed.
Dynamic linking defers linking until execution time: the in-memory program text carries a stub for each library reference — a piece of code saying where to find the routine in memory or on disk. On first execution the stub replaces itself with the routine’s address and runs it. All processes thus share one copy of each library routine, though sharing requires help from hardware and OS (shared memory).
Contiguous Memory Allocation
Contiguous allocation was common earlier in OS evolution. Understanding it is worthwhile because it introduces design issues that make you appreciate newer methods like paging and segmentation.
Here every process resides in some contiguous address range (say L addresses from B to B+L-1). Typically physical memory has two partitions: one for the OS and one for all user processes.
Protection suffices with a base-limit-like scheme: a user process works with L legal addresses from 0 to L-1; the MMU checks every generated address against the legal range, then maps it by adding the relocation register’s value. By changing these registers the OS tracks processes while relocating or resizing them.
Allocating Partitions
Fixed-size partitioning: the OS divides user memory into M equal partitions, allocating one per process. A process larger than the partition size cannot run at all. When a process exits, its partition returns to a free list.
Variable-size partitioning is more flexible: the OS maintains a free-list of available holes in memory. When a process must load, the OS finds — if possible — a big-enough hole, removes it from the list, places the process at its start, and any unused remainder becomes a new hole back on the list. When a process terminates, its memory frees up, and the OS checks whether adjacent free holes can merge into a bigger one:
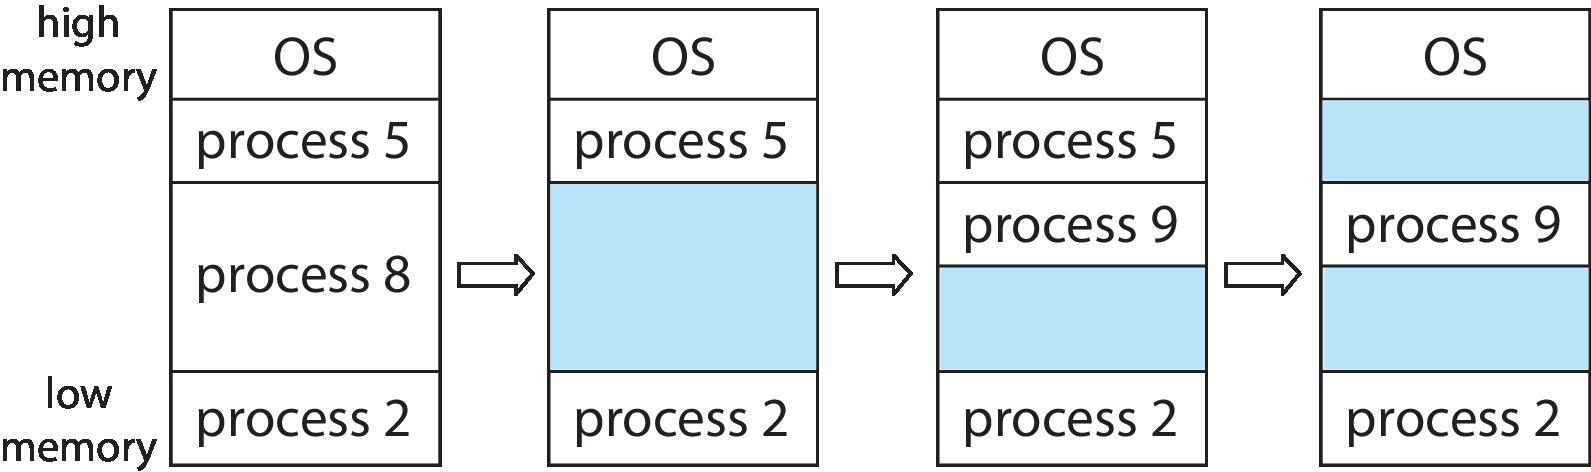 Figure (4): Holes under variable partitioning
This raises the classic dynamic storage allocation problem: how to satisfy a request of size N from a list of free holes? The search strategy affects performance:
- First-Fit: take the first hole big enough and stop searching.
- Best-Fit: take the smallest hole big enough — smallest leftover. (Keep the list sorted by size to speed search.)
- Worst-Fit: take the biggest hole — biggest leftover.
Simulations found first-fit and best-fit faster than worst-fit and able to satisfy more requests; first-fit is generally faster than best-fit, with no clear winner between them on satisfying more requests.
Fragmentation
Fragmentation comes in two kinds:
External fragmentation: memory available but unusable — especially a collection of holes, each too small for anything, yet together enough for a process if they could combine. Severe external fragmentation inevitably occurs under first/best/worst fit; after many allocations and deallocations perhaps a third of memory may go wasted.
Internal fragmentation: memory allocated but unused — allocation schemes may force giving processes more than they need (minimum allocations, fixed-size chunks).
If processes were dynamically relocatable, the OS could move them around to compact external fragmentation into usable holes — but compaction takes long if done all at once and becomes tricky piecemeal.
The elegant escape — coming right up — is an end run around external fragmentation entirely: letting a process’s allocation consist of fixed-size non-contiguous chunks of physical memory called page frames.
Paging
Paging replaces contiguous allocation; with it there is never any external fragmentation — hence no need for compaction.
The Basic Method
Assume the smallest addressable unit is a byte, and hardware defines a page size such as 4KB (4096 bytes). We divide primary memory and backing store into page-sized contiguous chunks called frames: frame #0 spans bytes 0–4095, frame #1 bytes 4096–8191, and so on:
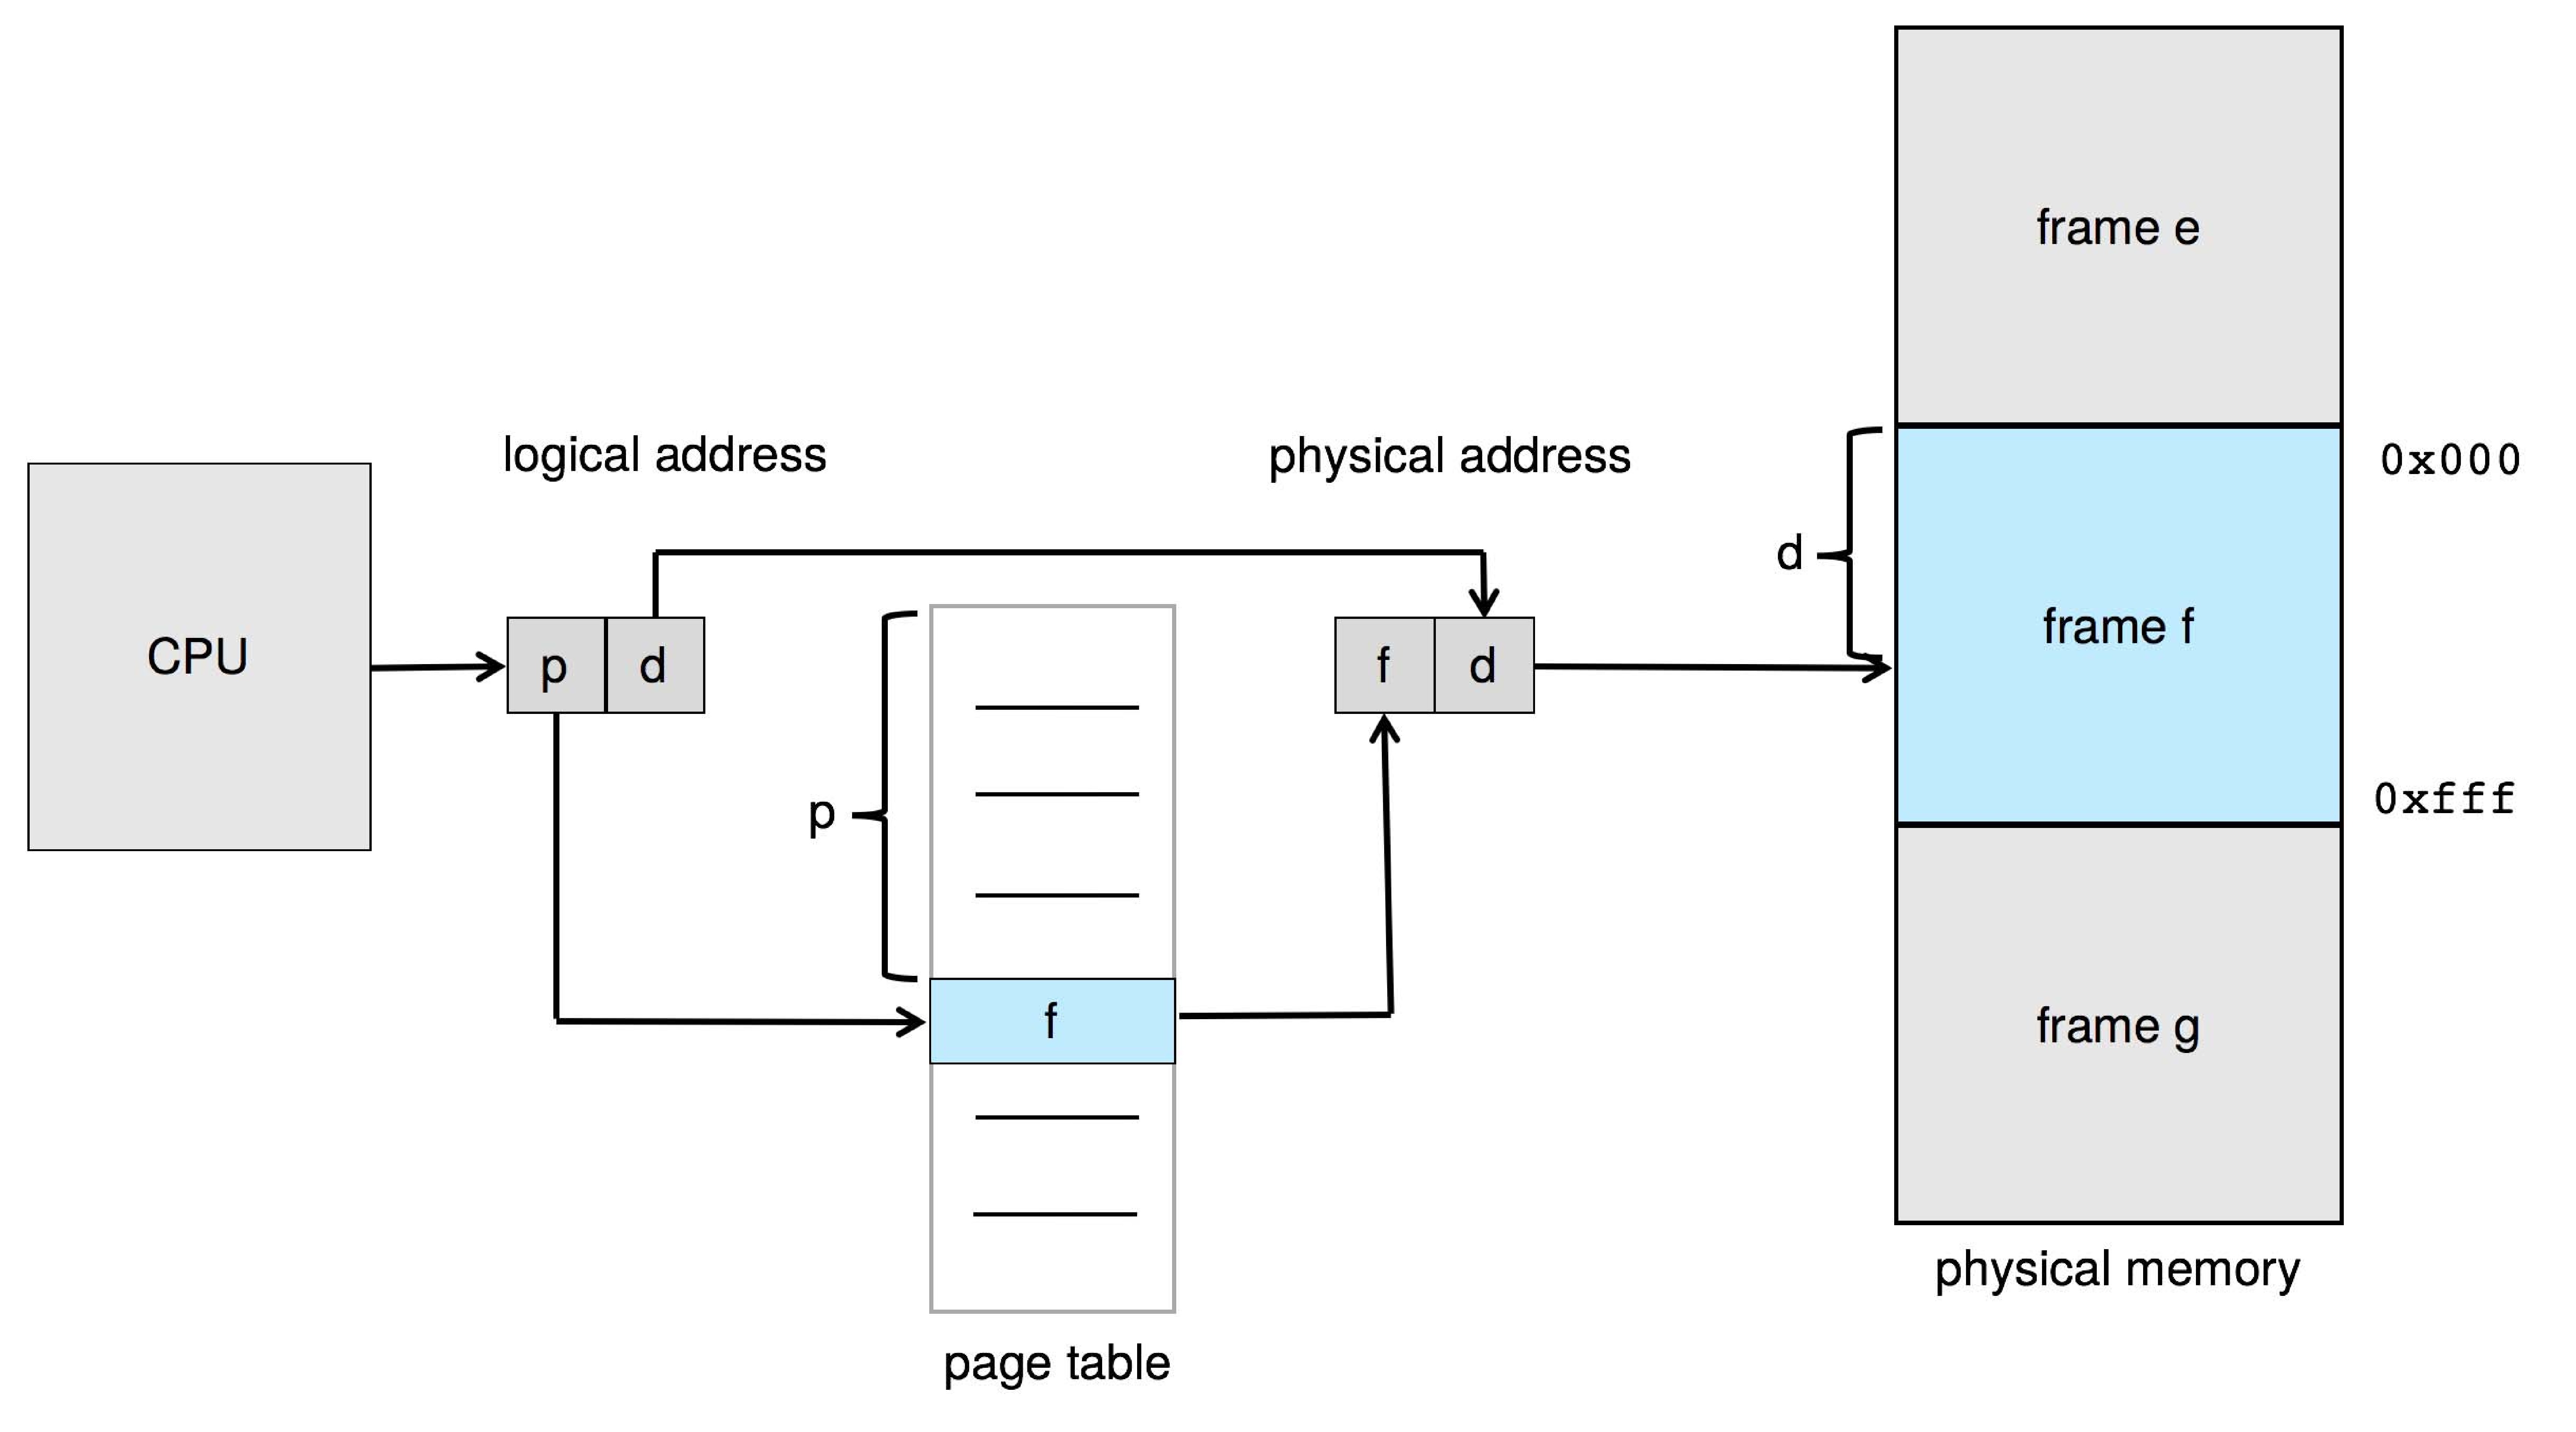 Figure (5): Paging hardware
The OS creates a page table entry when first loading each page into a frame: logical page i gets the frame number assigned to it placed at entry i of the process’s page table. When the process accesses memory, hardware uses some most-significant bits of the logical address — the page number — as an index into the table.
Visualize the logical address as (p | d): p the page-number bits and d the remaining bits called the offset. Hardware finds frame number f at location p in the table, then builds the physical address (f | d) by substituting f for p — p and f may differ in bit length — and proceeds with the access.
If page size is 2ⁿ bytes, each offset consists of n bits. If logical memory is 2ᵐ bytes, the page number has m−n bits.
The tiny worked example:
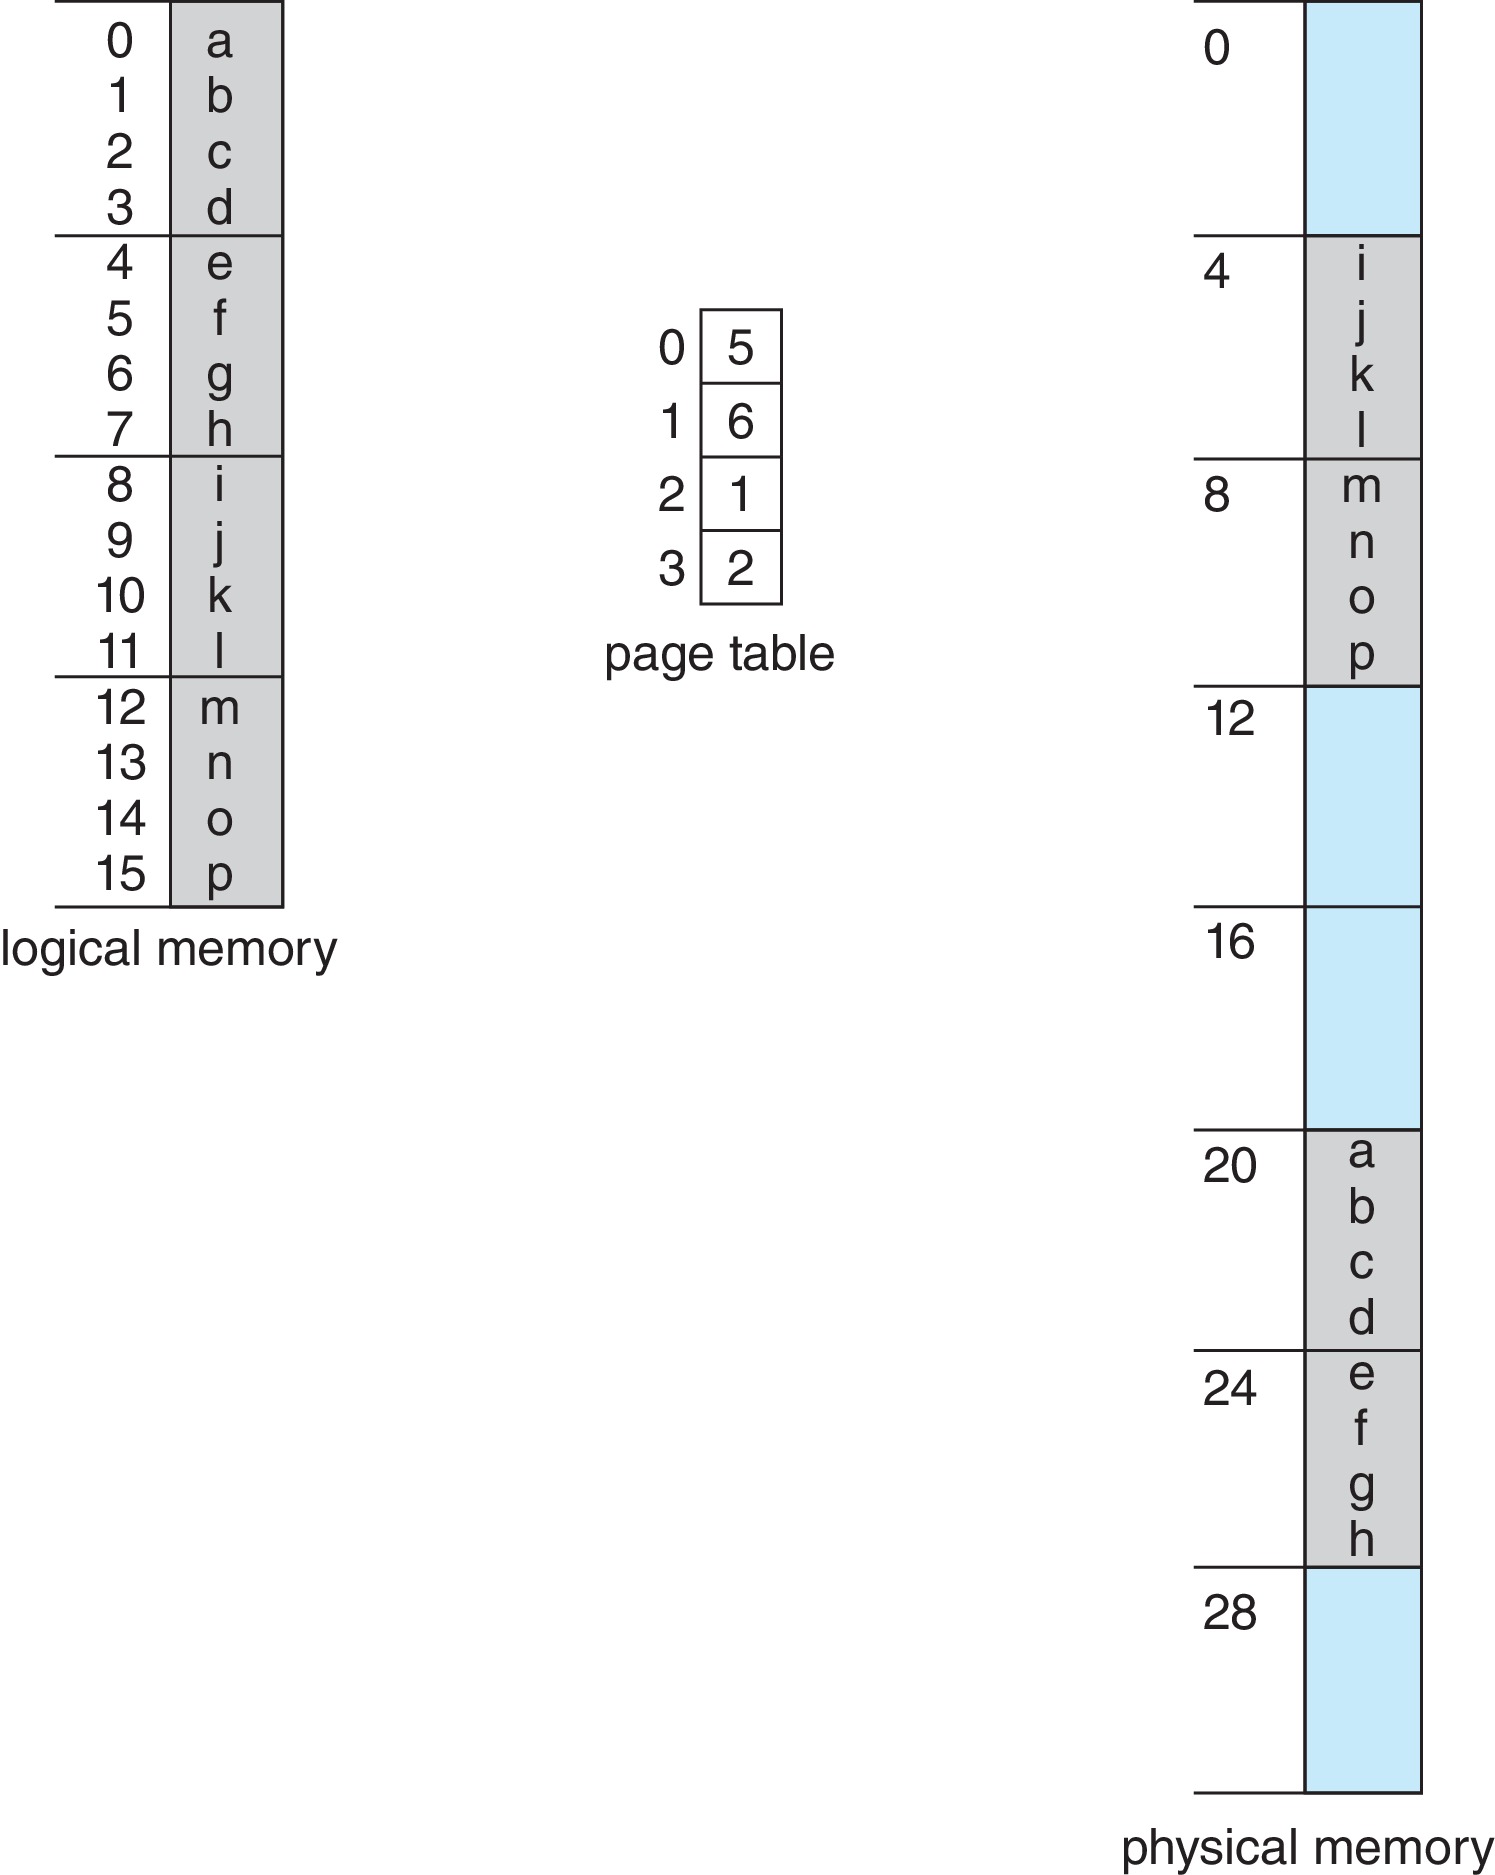 Figure (6): 16-byte logical memory with 4-byte pages
Page size is 2² = 4 bytes, logical memory is 2⁴ = 16 bytes, physical memory is 2⁵ = 32 bytes. The table maps logical page 0 to physical frame 5, and so on. Let us translate logical address 13:
13 in binary    = 1101
offset      d   = 01
page number p   = 11 = 3
page table      : page 3 → frame 2 = 10
physical addr   = (10 | 01) = 1001 = 9
And we see the stored value at physical address 9.
With paging there is no external fragmentation — but typically a process does not use all of its last frame; the remainder is internal fragmentation, about half a page on average. Small pages reduce internal fragmentation; large pages keep the page table smaller and cut I/O overhead moving pages to/from backing store — a classic trade-off.
To put a process into memory, the OS writes its code and data structures into a set of frames that need not be contiguous — while its logical space remains contiguous, just an array of bytes from zero to some upper limit.
Protection with paging is straightforward: the OS creates the page table and uses it to protect memory much as others would use base-limit registers — the “bases” are frame numbers, and the “limits” are implicitly equal to the page size. A process simply cannot address memory outside its page table. The OS also tracks all frame allocations through a frame table structure and keeps a copy of each process’s page table.
One important distinction: when the OS itself needs a logical-to-physical translation (say, a user passes a logical buffer address as a parameter for an I/O syscall), it uses its own copy of the page table to translate manually. Routine translation during the fetch-decode-execute cycle, however, is performed by hardware — not the OS.
Hardware Support: PTBR & the TLB
Page tables can be implemented various ways. In an extremely simple case, each process gets its own bank of dedicated registers — but register counts are limited, ruling out larger tables.
Many contemporary systems give the CPU/MMU architecture a page-table base register (PTBR) pointing to a large table resident in main memory. This speeds context switches: installing the new process’s table just means changing one register’s value.
But an in-memory table costs two memory accesses per reference — one to look up the frame number, a second to fetch/store the actual data.
To avoid halving memory speed, contemporary systems add a fast associative cache called the Translation Look-Aside Buffer (TLB), so the MMU usually avoids touching the page table during translation:
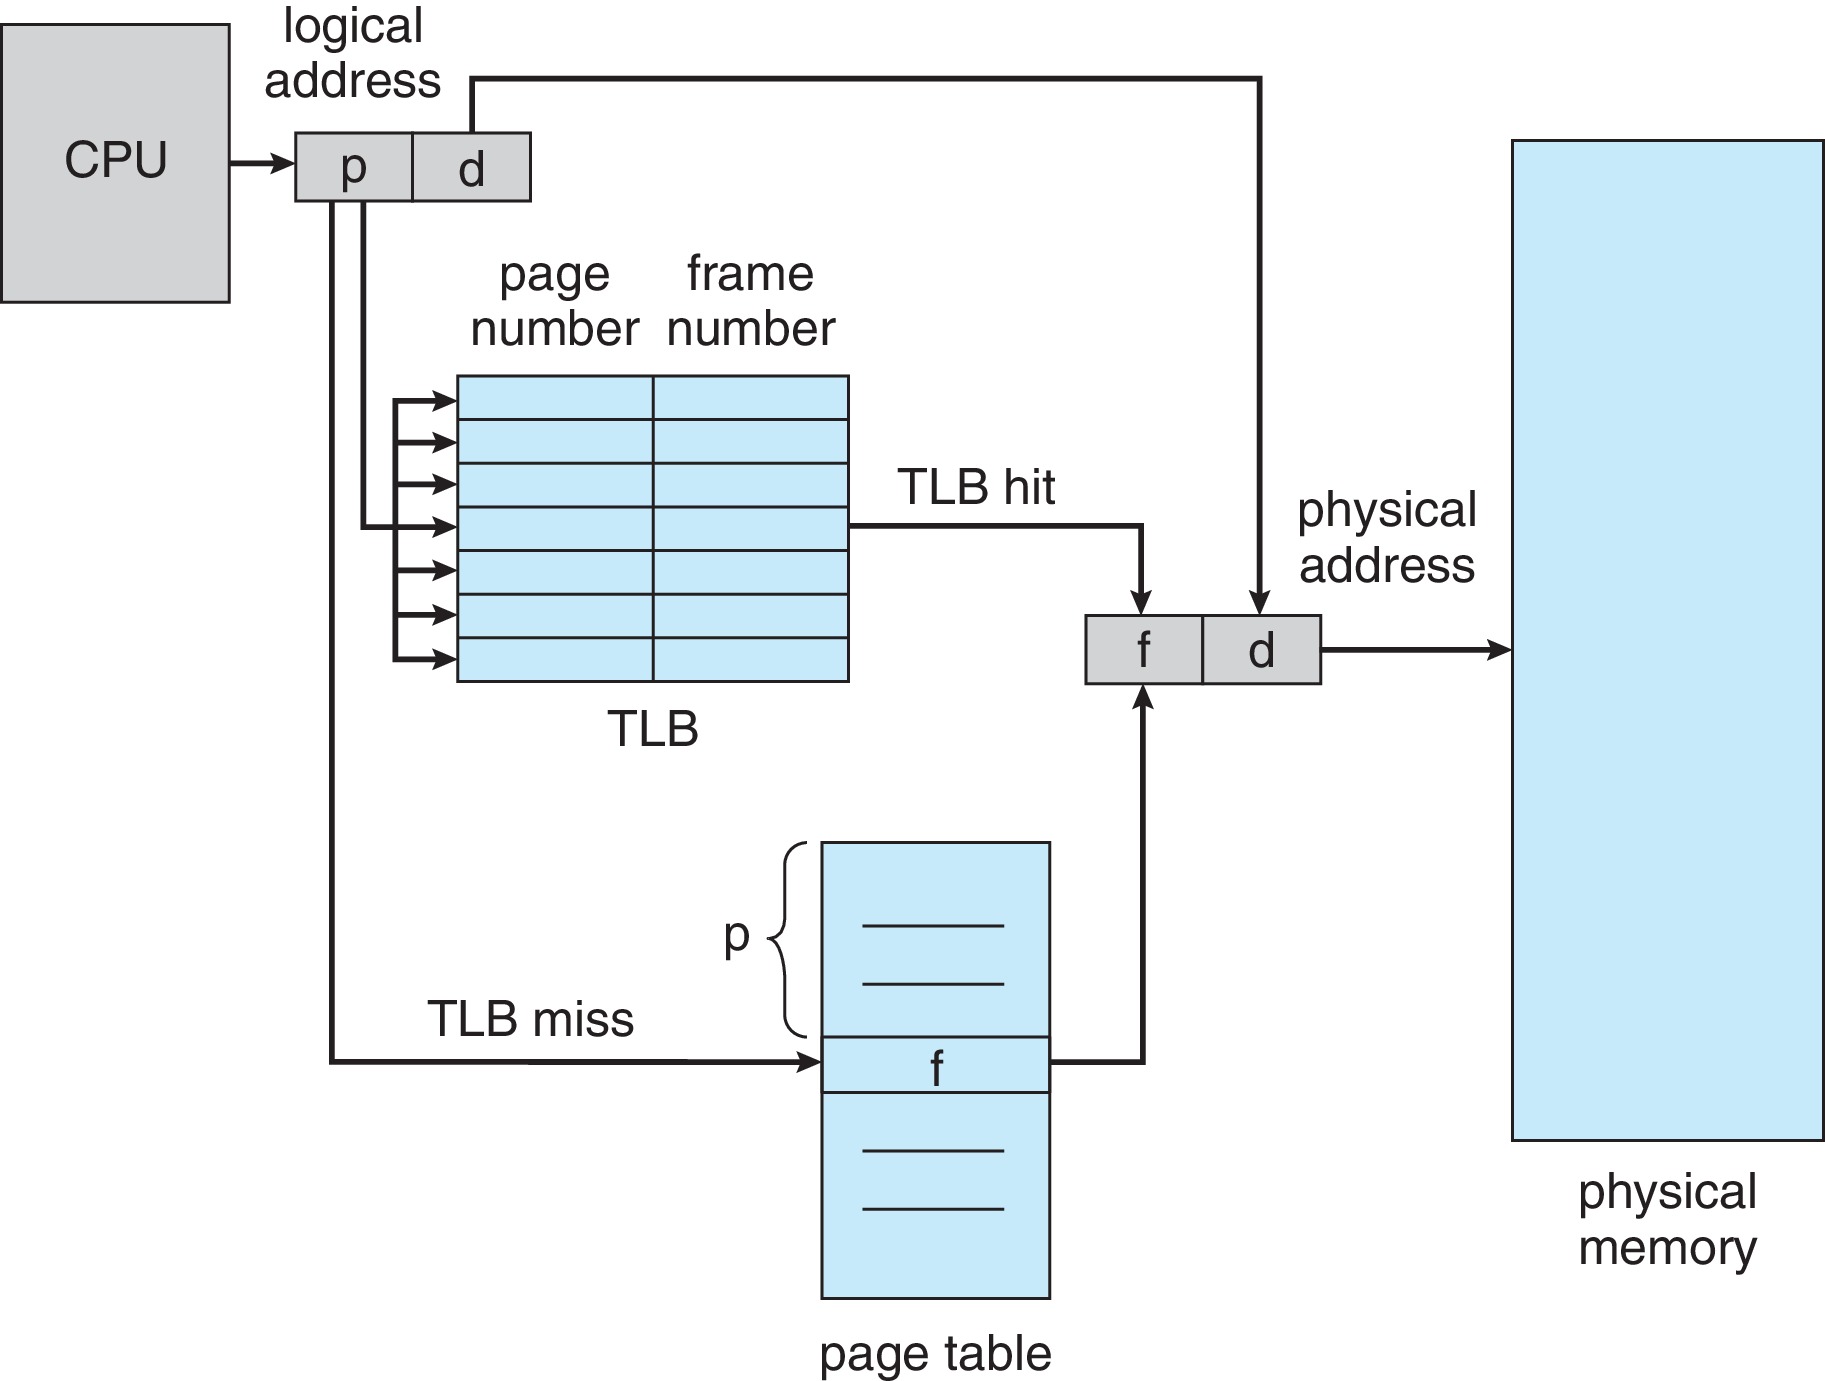 Figure (7): Paging hardware equipped with a TLB
Hardware checks the TLB first: on a hit translation completes immediately; on a miss the page table is consulted and the found information inserted into the TLB for future use — overwriting an existing entry if full. Address Space Identifier (ASID) technology lets the TLB hold translations for several processes at once, cutting down time-consuming cache flushes on context switches.
Effective Access Time (EAT) is a function of hit ratio, memory access time, and TLB search time. For example, with a 90% hit ratio and 12ns memory access:
EAT = 0.9 × 12 + 0.1 × 24 = 13.2 ns
Notice the effect: without a TLB we would double the time; with a high hit ratio we stay near the original.
Protection & Shared Pages
Some bits in page table entries enforce restrictions — a read-only bit, for instance: hardware generates a trap if a user process attempts writing such a page. A valid bit is also common; some systems size the table to the process with a page-table length register (PTLR), so reaching past the table’s end traps. Unfortunately a process can generally still touch the internal fragment inside its last page.
Paging supports shared memory easily: if two processes’ page tables contain the same frame number, they share that frame. The OS uses this to let many processes share read-only program text — the standard C library, say — and writable memory can be shared as interprocess communication.
Structure of the Page Table
Modern page tables are huge! Let us see why:
A typical page table entry is 4 bytes, and a typical page is 2¹² = 4KB, so one page fits a thousand table entries (1024). With a 32-bit address space there are 2³² addressable bytes; with 4KB pages, 20 bits remain for the page number — meaning up to 2²⁰ pages, roughly a million pages per process!
Under those assumptions a process’s page table would span 2²² bytes — itself covering 2¹⁰ = 1024 pages. To avoid solving a storage-allocation problem just to place the table, the tables themselves can be paged.
Hierarchical Paging
One scheme partitions the logical address as (P1 | P2 | d):
- P1 indexes the outer page table.
- The entry found there is the frame number of one page of the page table itself.
- Then P2 and d complete the translation the usual way: P2 indexes into that specific page of the table, and the resulting frame number combines with d to form the physical address:
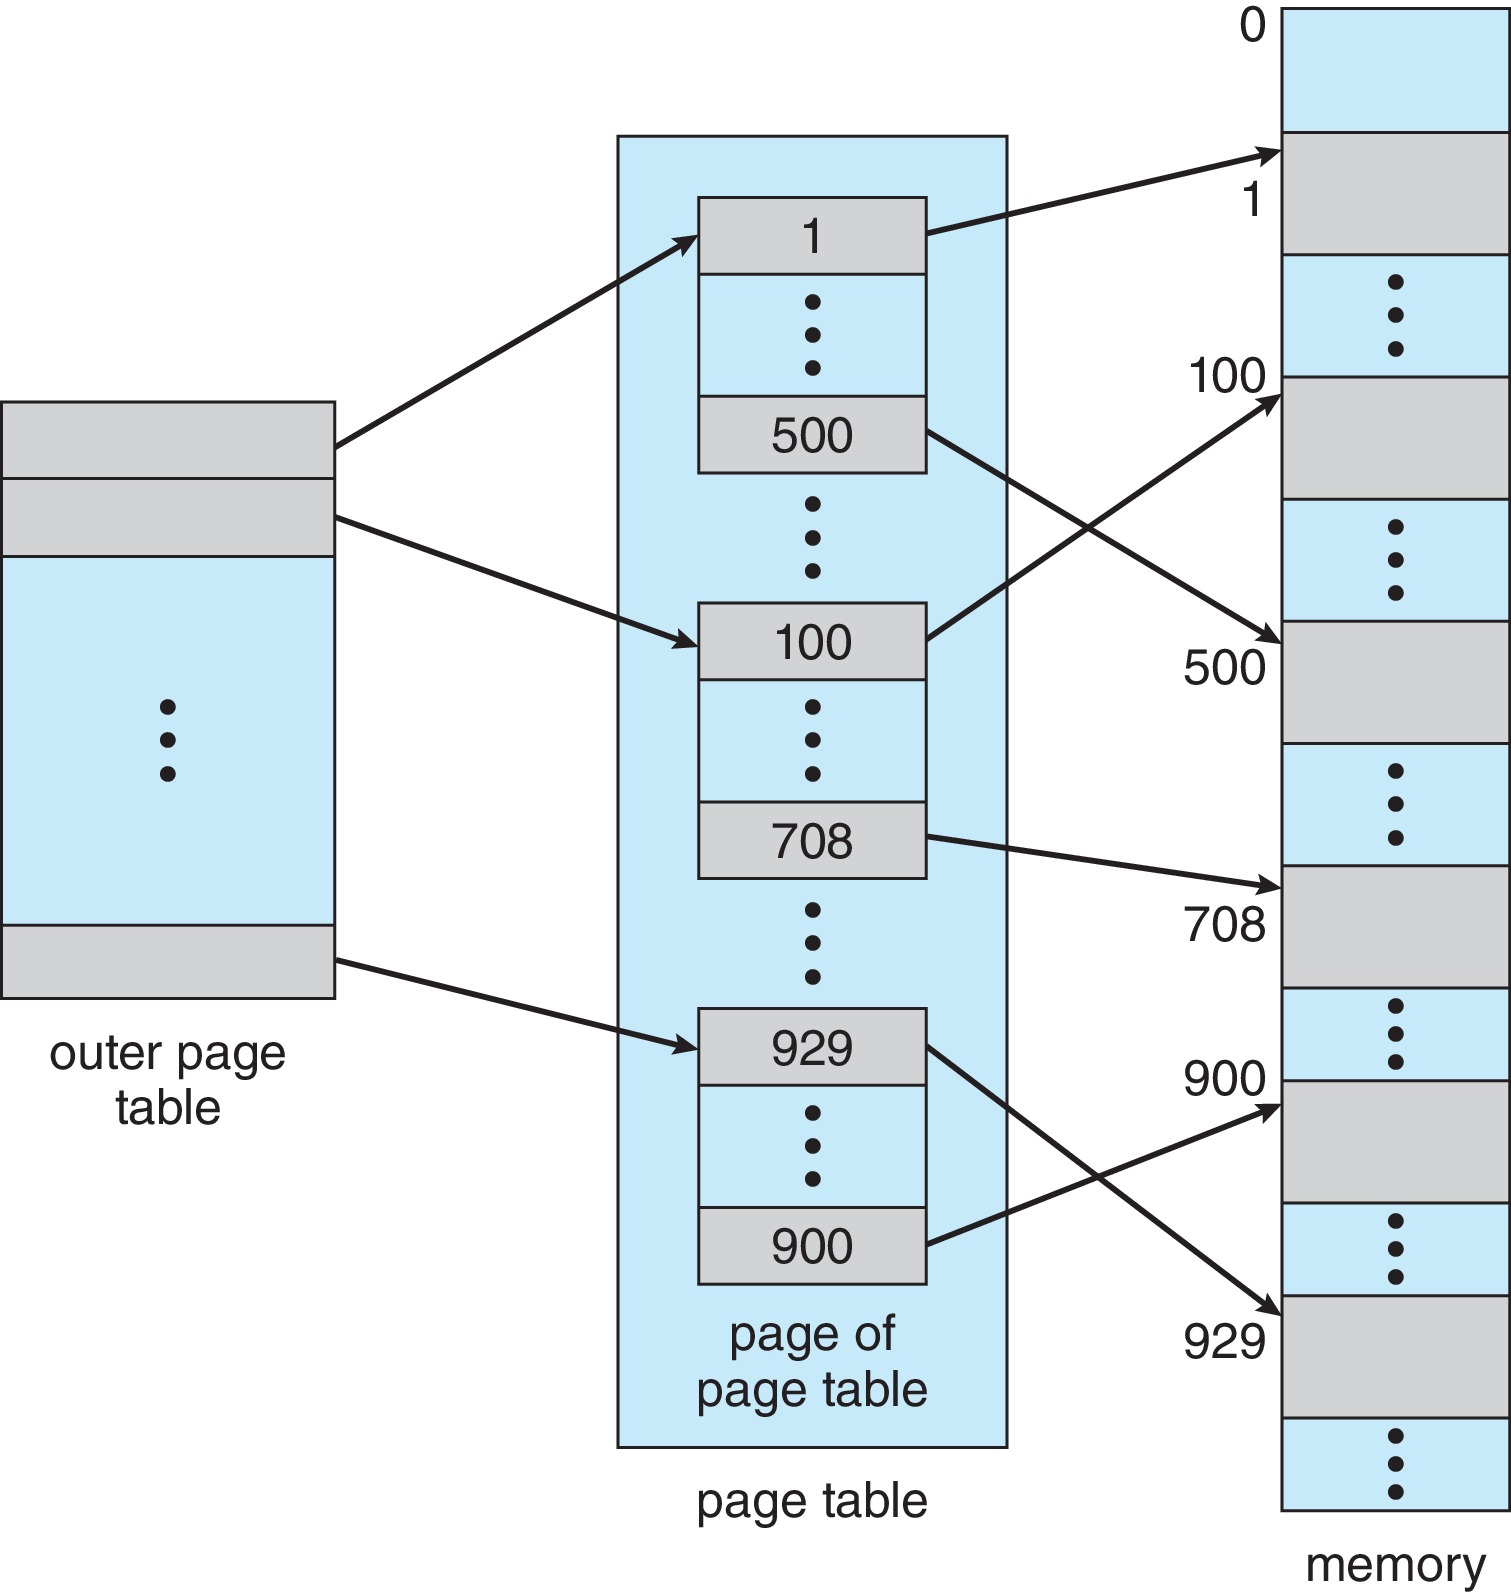 Figure (8): A two-level page-table scheme
For even larger tables some architectures supported deeper hierarchies — certain SPARC processors three levels, Motorola 68030 four. But 64-bit spaces are generally considered unsuitable for traditional hierarchical tables: seven levels would be required.
Hashed Page Tables
A per-process alternative: apply a hash function to the virtual address, resolving collisions with external chaining; each chain entry carries a virtual page number, frame number, and next-pointer. Clustered page tables are a variant where each entry refers to several pages at once.
Inverted Page Tables
Systems like UltraSPARC and PowerPC used an innovation called the inverted page table: one entry per frame — not per virtual page — identifying which address space (process) uses the frame and which virtual page number it backs. One inverted table serves the whole system, rather than one per process:
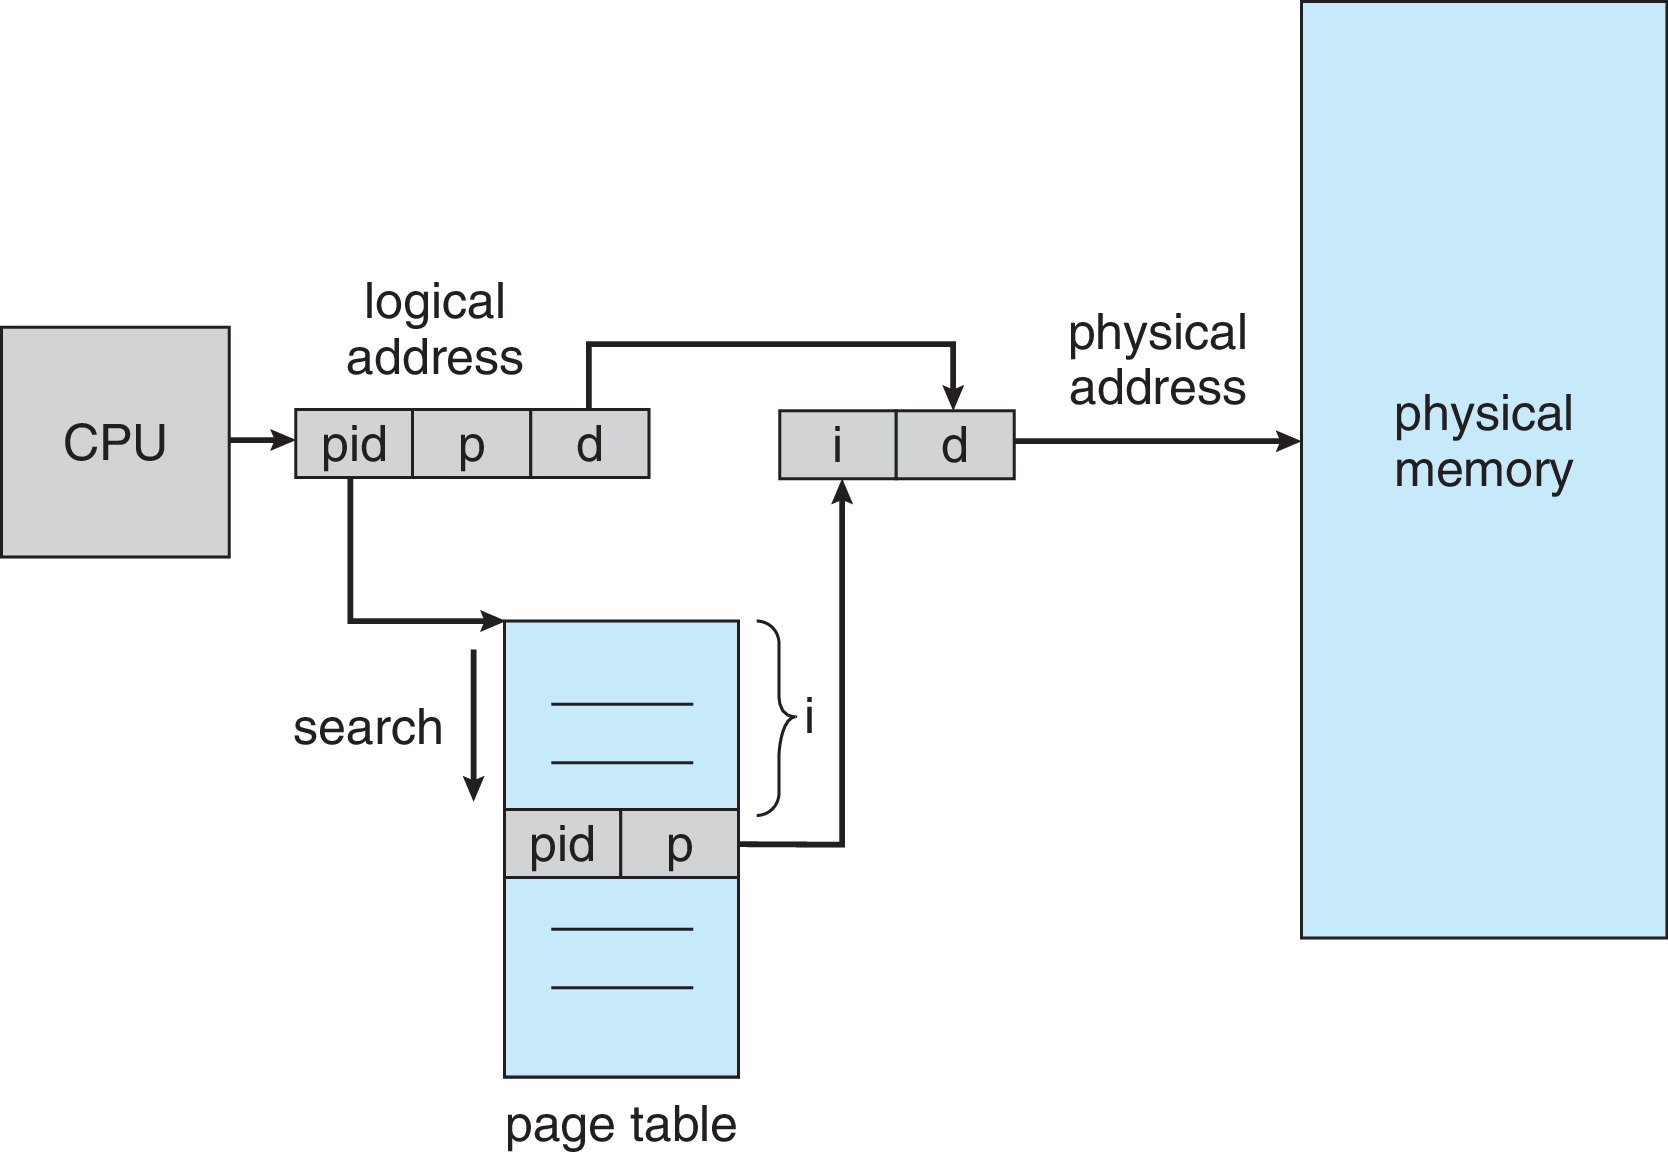 Figure (9): Inverted page table structure
The clear advantage: table memory is bounded by a constant times physical memory size, instead of being bounded by process count and maximum virtual space. The clear disadvantage: neither hardware nor OS can index directly by page number, so forward translation lookups could take a long time — though this structure easily supports reverse translation. Hence hashing joins in: apply a hash to the address-space ID plus virtual address to pick the first probe location, then follow chains until the matching entry appears. Naturally, on a TLB hit nobody touches the table and EAT approximates plain memory access time.
Swapping
Standard swapping: temporarily take main memory away from one process and hand it to another. If we take X’s memory away, we first copy X’s contents — text, data, and much of its context — to secondary storage (X is swapped out), then give the memory to other processes. The OS retains enough about X to find it later and copy it back (swap it in) to resume execution. A swapping system can multiprogram more processes than physically fit in memory at once. Long-idle processes are good swap-out candidates.
But standard swapping is impractical in modern systems — swapping whole processes takes too long. Far more common is swapping individual pages of a process; at any moment only a small proportion of any process’s pages will likely be swapped out.
And mobile systems? They typically skip swapping because:
- Swapping demands large secondary storage mobile devices lack.
- Throughput between main memory and flash is slow.
- Swapping quickly burns through flash’s limited write cycles.
Instead, iOS asks applications to relinquish unneeded memory and may terminate those that do not free enough. Android acts similarly, except before killing an over-using process it saves its state to secondary storage so the app restarts quickly. Mobile programmers therefore build conservation-minded allocation habits into their apps.
Real-World Snapshots
IA-32 (Intel 32-bit): combines segmentation and paging. The logical address is a (selector, offset) pair; the segmentation unit — part of the MMU — turns it into a linear address by adding the offset to the segment base (exceeding the limit traps). The paging unit then translates linear to physical:
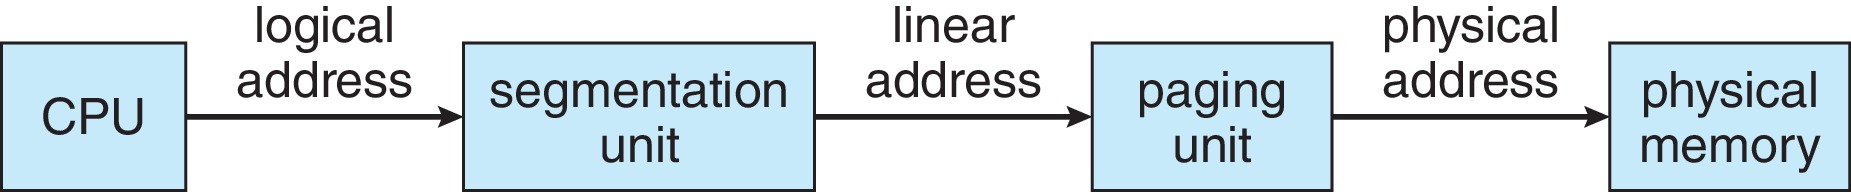 Figure (10): Logical to physical translation in IA-32
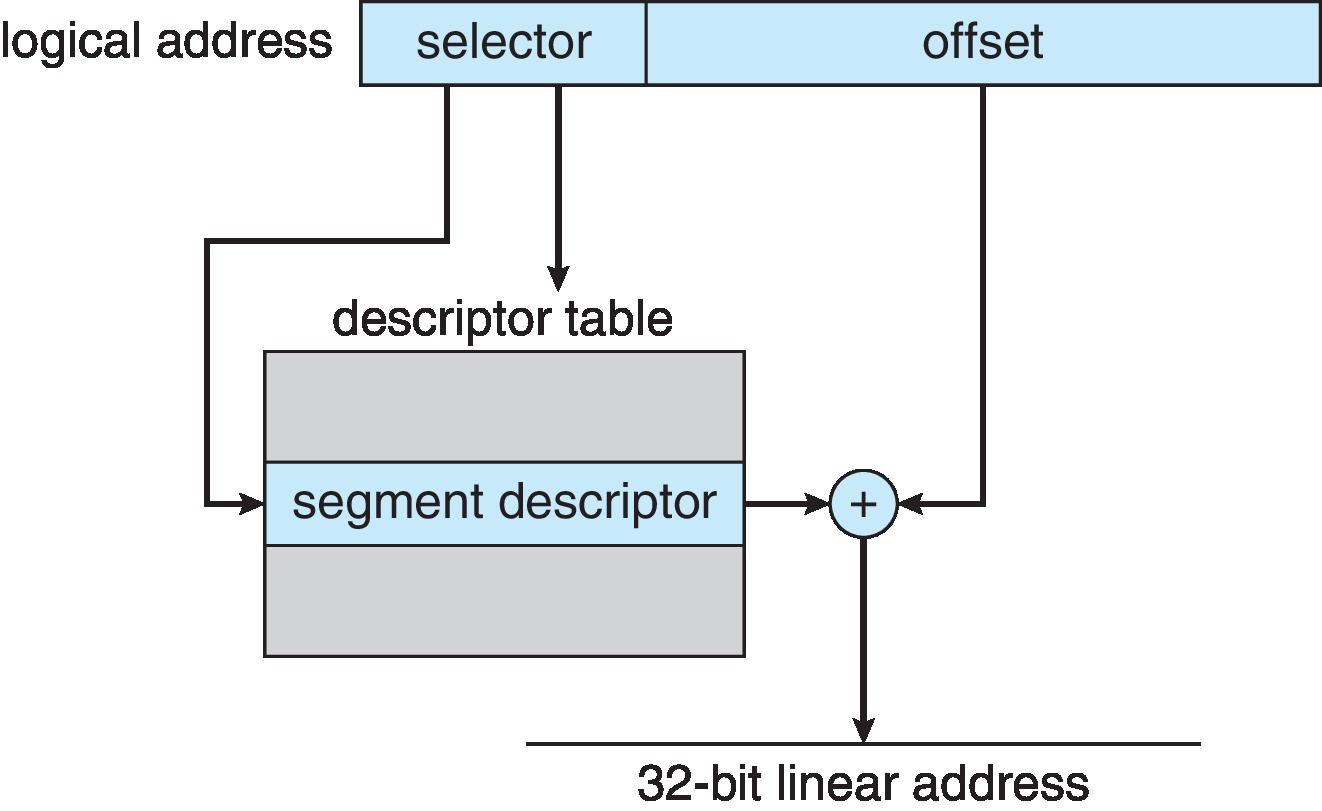 Figure (11): The IA-32 segmentation unit
Two page sizes are supported, 4KB and 4MB, via a Page Size Flag in the outer table — unset means standard two-level translation, set means single-level using only the outer table:
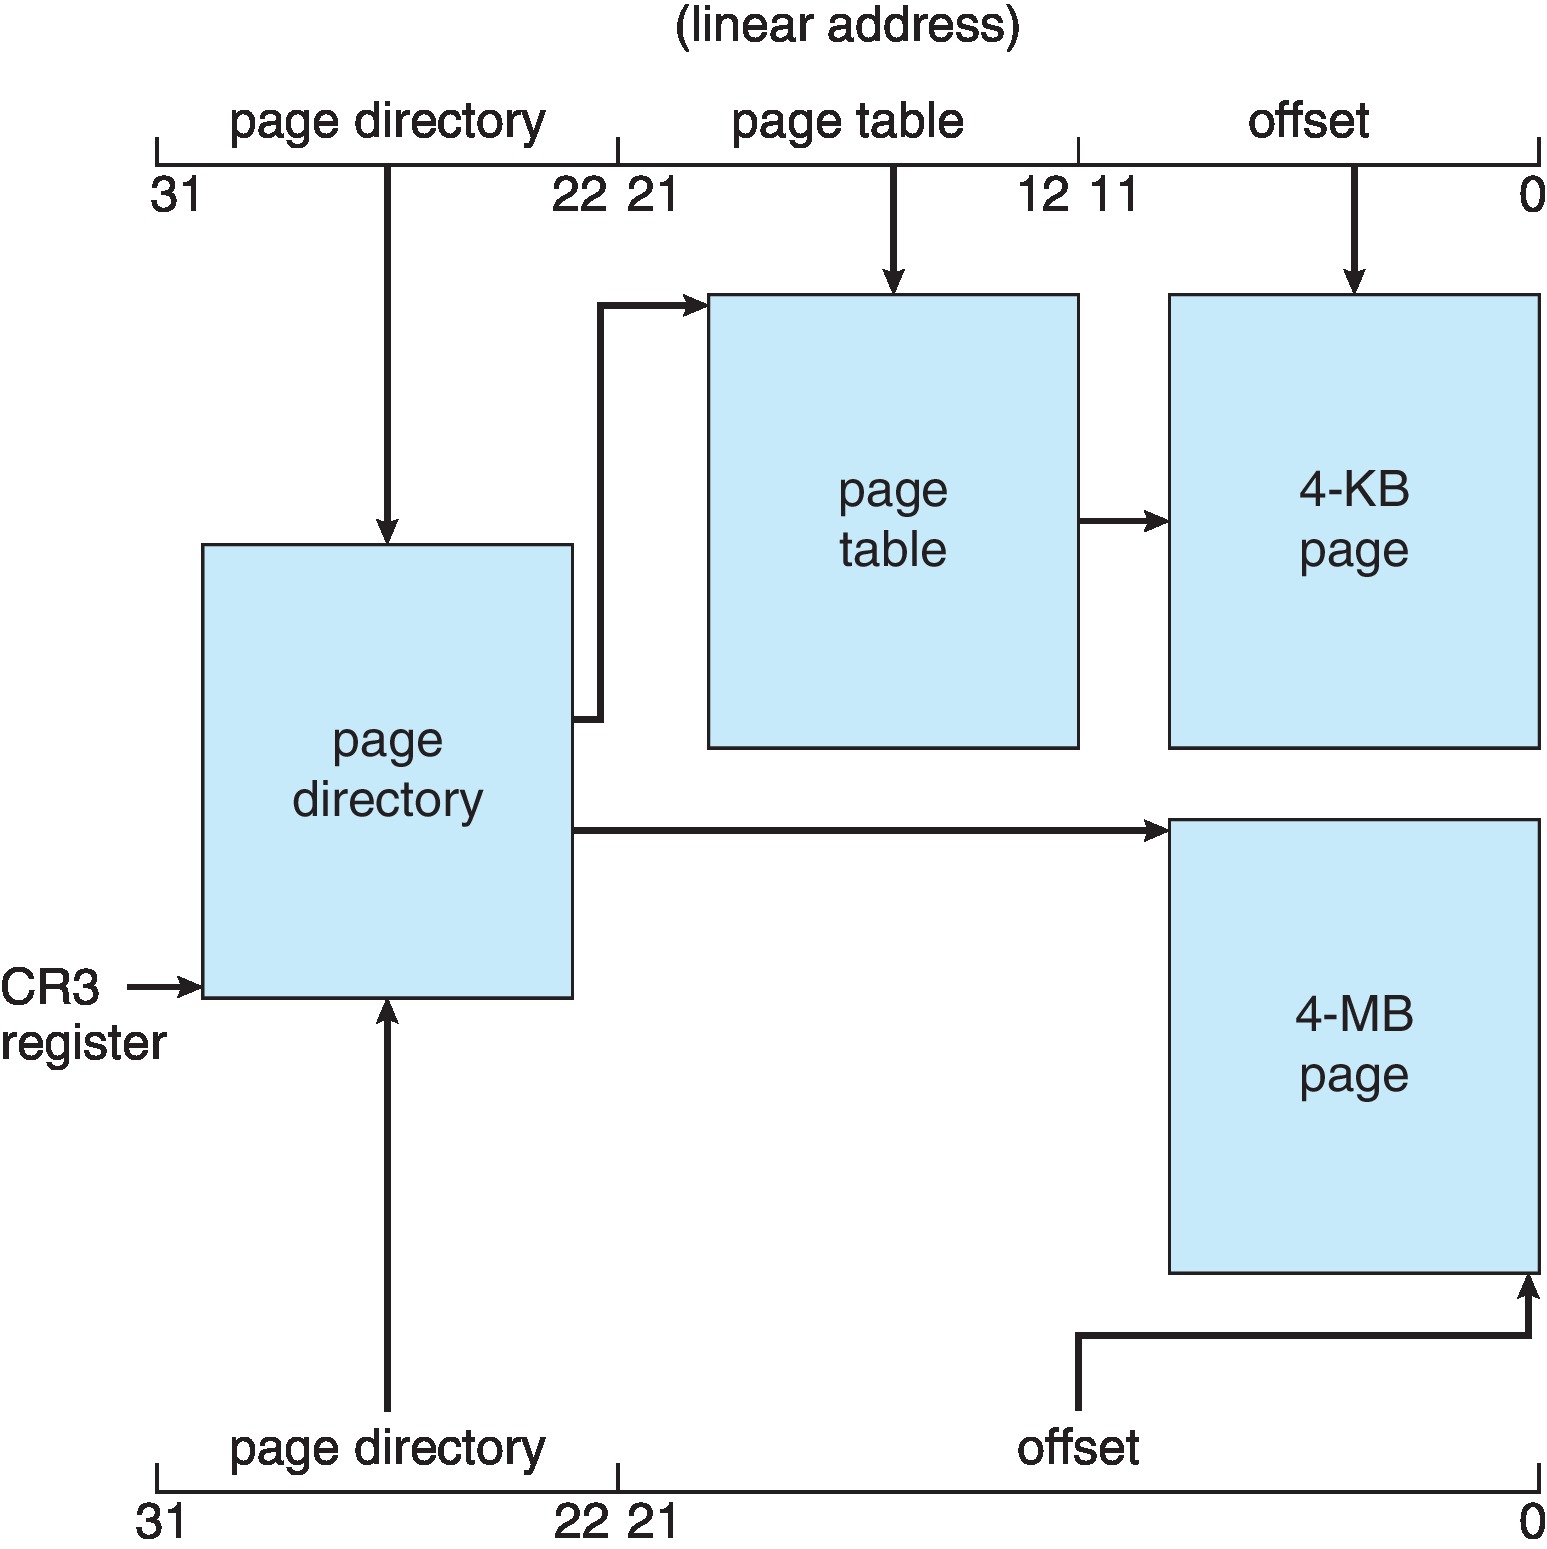 Figure (12): The IA-32 paging unit
x86-64: developed by AMD and adopted by Intel; potentially 64-bit address spaces, with current systems supporting up to 48-bit virtual and 52-bit physical addresses.
ARMv8: the architecture common in mobile devices, supporting 4KB, 16KB, and 64KB pages plus contiguous regions of 2MB, 1GB, 32MB, and 512MB. It features two TLB levels — separate inner micro-TLBs for instructions and data, ASID-aware — falling back to an outer main TLB on misses, and if page-table walks become necessary, ARM hardware performs them itself:
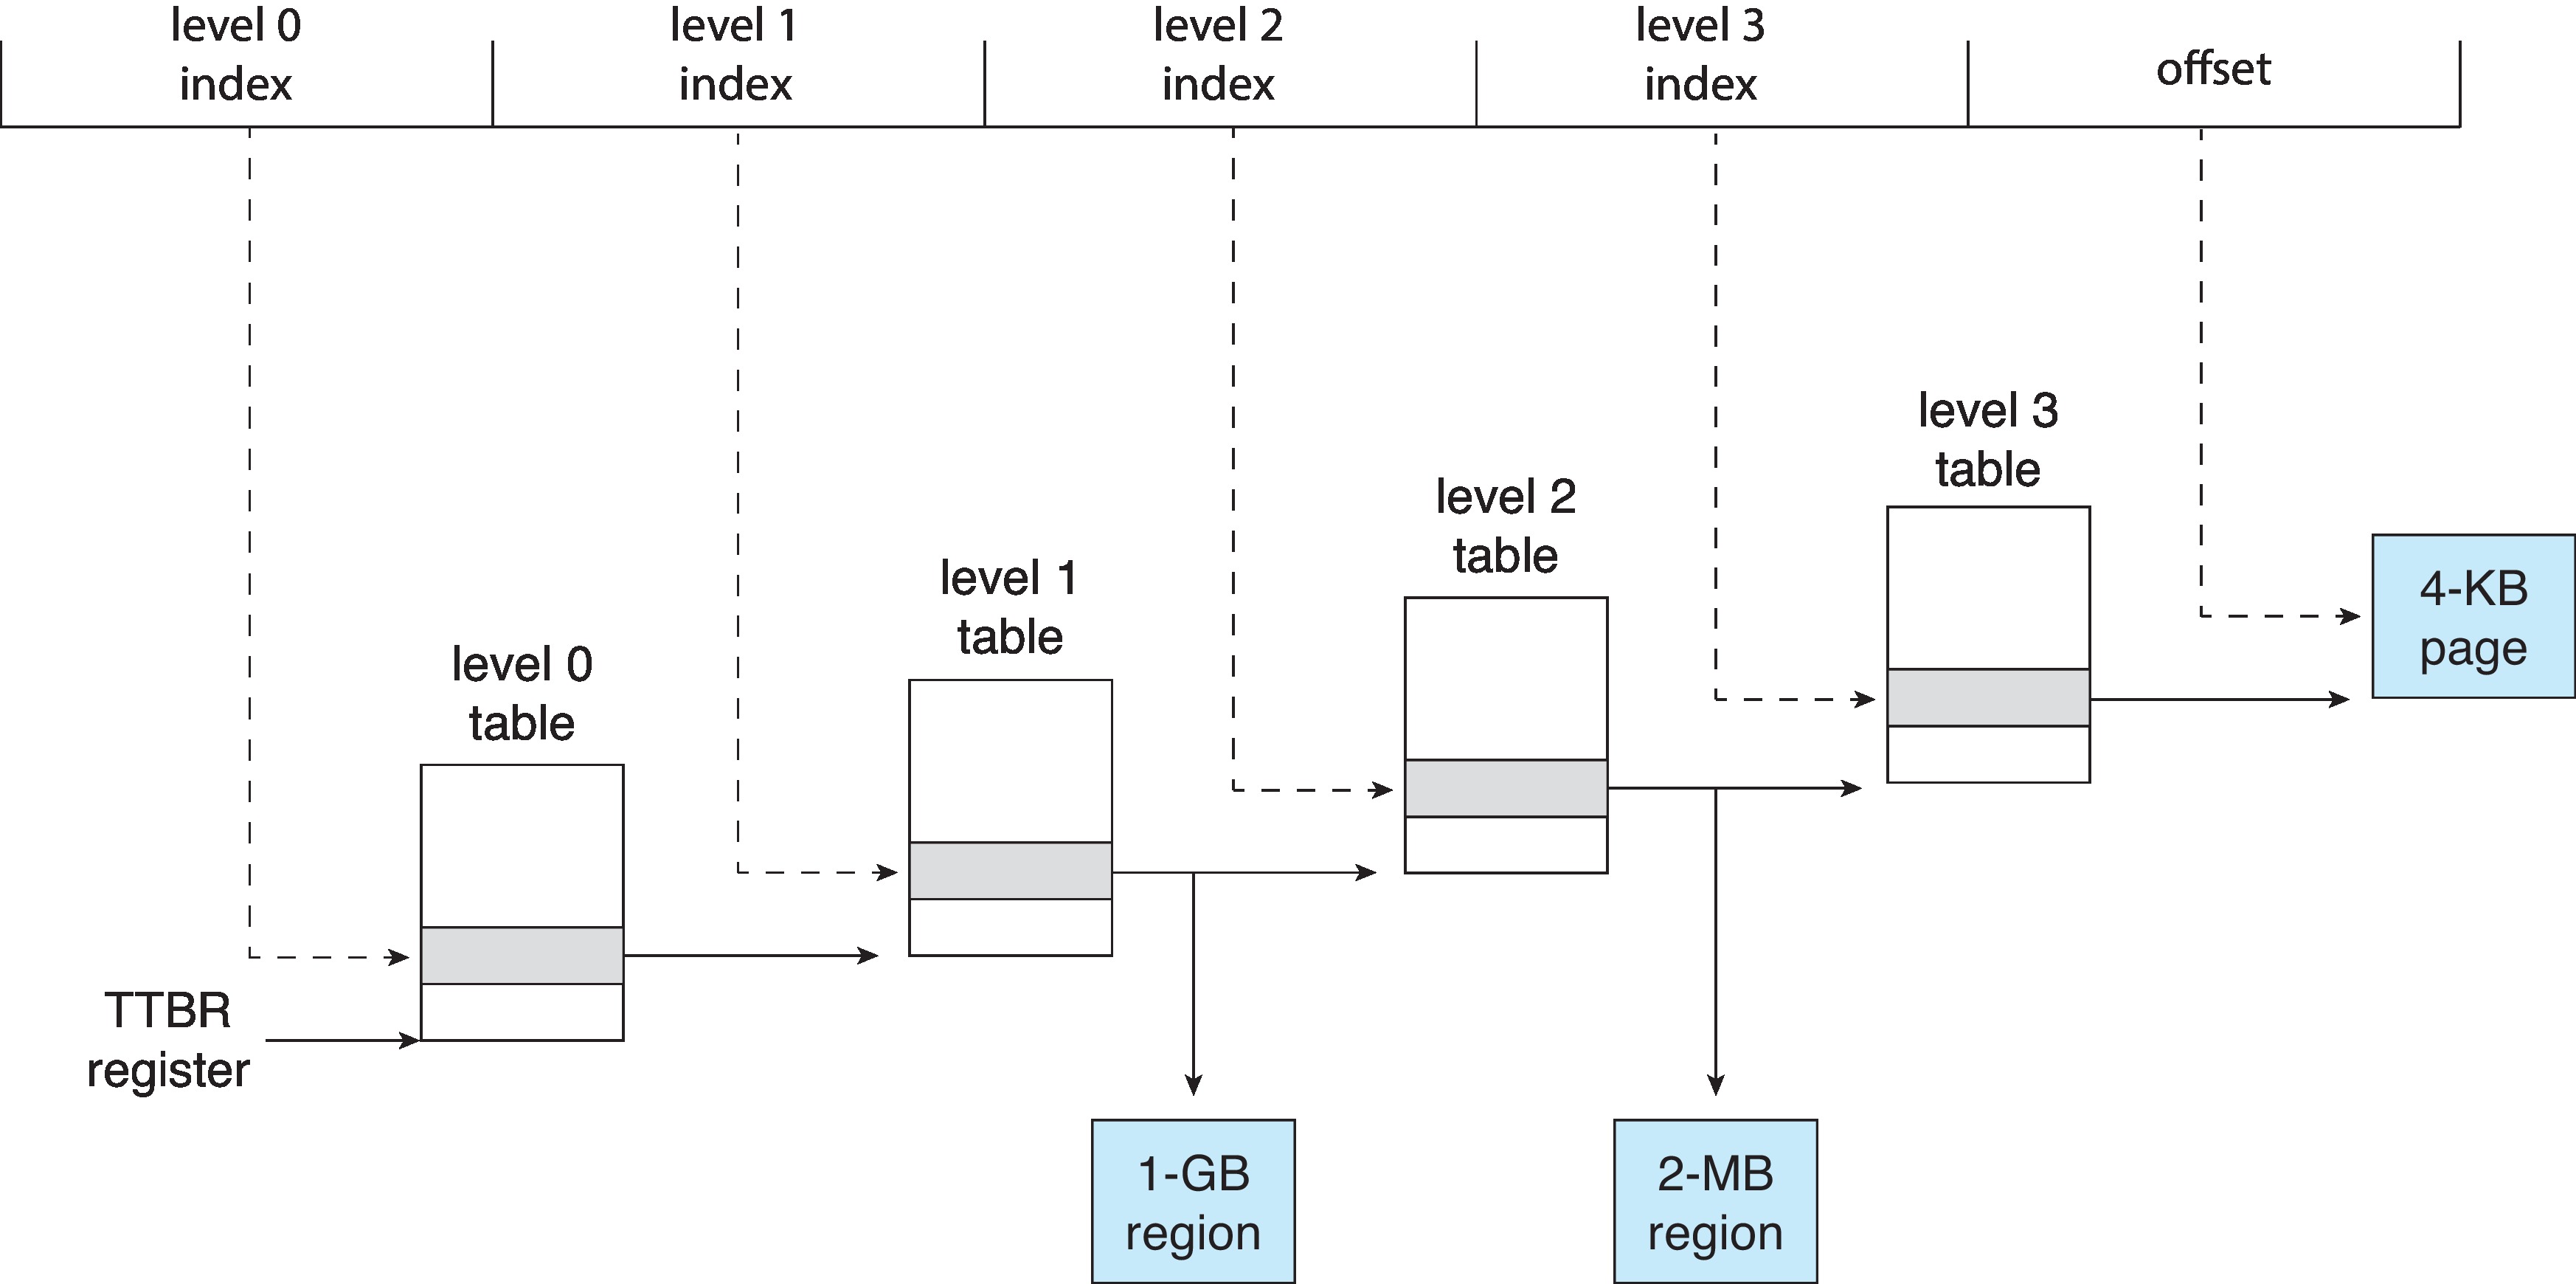 Figure (13): Four-level hierarchical paging on ARMv8
Now you understand how an OS manages memory — from primitive contiguous allocation to modern paging and TLB-backed translation. See you in the next lesson, God willing.
Keep us in your prayers.